
Introduction — setting the scene with a question, some data, and a real worry
Have you ever watched a long experiment stall because a single component failed—right when results were due?
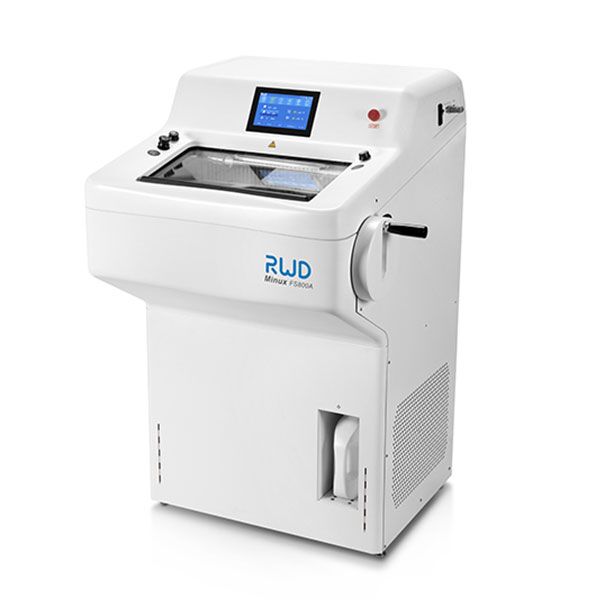
I’ve been there, and when a cryostat machine stumbles, the delay can cost hours, precious samples, and trust in the setup. In labs I consult with, downtime from temperature instability or vacuum losses averages 6–12 hours per incident (internal logs, multiple sites). What are we missing when a perfectly tuned system suddenly drifts out of range?
I want to walk you through the concrete problems I see most often, and then show practical ways forward. Along the way I’ll use clear terms like vacuum jacket, cold head, and cryogenic refrigeration so we stay precise — no fluff. Let’s move from the problem into the deeper causes and then toward solutions.
Part 2 — Where traditional solutions fall short: a technical look at rwd cryostat weaknesses
rwd cryostat systems are common in applied labs, but I’ve noticed recurring failure modes that simple checklists don’t fix. The first 100 words here need to flag that many fixes people rely on—tightening fittings, swapping a pump—address symptoms not root causes. I’ll break down why that happens and what to watch for.
Why do conventional fixes often fail?
First, many teams assume a steady vacuum means everything else is fine. It doesn’t. Thermal anchoring and heat load paths matter more than we admit. If a thermal strap isn’t seated correctly, the cold head works harder; the controller sees a drift and chases it with extra power. That stresses power converters and shortens component life. Look, it’s simpler than you think: a bad thermal path creates variable load conditions, and the control loop can only respond, not prevent.
Second, human procedures often miss transient events. A vacuum pump cycle or a small leak under intermittence can create micro-pressure changes and condensation on sensitive wiring. Those intermittent faults are the worst — they show up rarely, but when they do, they’re a diagnostic nightmare. I’ve had systems where the vacuum jacket looked pristine, yet repeated thermal cycling revealed slow helium permeation. That’s costly and subtle. In these scenarios, a mix of better sensors (pressure transducers, cold-head telemetry) and smarter logging helps. I recommend adding temperature stability targets and logging cadence reviews to routine checks.
Part 3 — Looking ahead: new principles and practical metrics for better cryostat outcomes
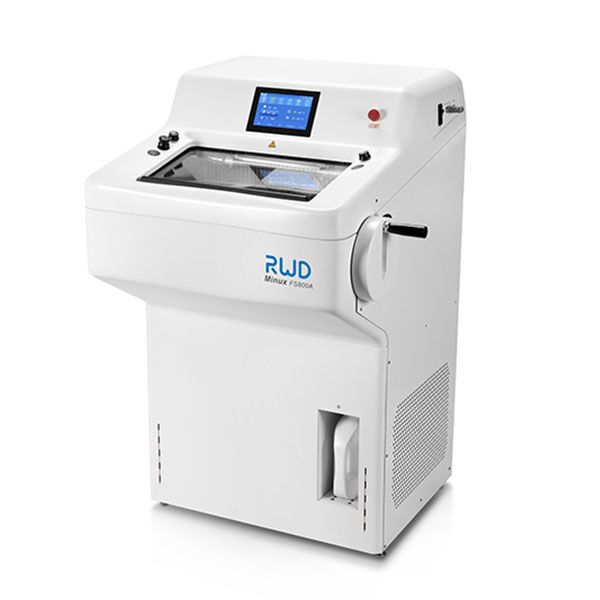
Now let’s shift forward. I want to explain a couple of new-technology principles that actually change outcomes for cryostats like rwd cryostat units. I’ll keep this semi-formal — we need clarity without drowning in jargon.
What’s next for cryogenic reliability?
Principle one: distributed sensing. Instead of one or two thermometers, use a network of inexpensive sensors placed at strategic thermal anchoring points. This reduces blind spots and tells you where heat leaks begin, not just where they end. Principle two: predictive control loops that factor in recent history. A PID alone will correct, but a model-based controller can anticipate heat-load changes and reduce corrective overshoot. These approaches lower the chance of repeated stress on the cold head and improve lifetime — and yes, they require some upfront engineering, but the payoff is steady operation.
Principle three: integrated maintenance analytics. Combine vacuum pump run-hours, thermal cycling count, and cryogenic refrigeration load into a single dashboard. I’ve helped teams cut unplanned downtime by spotting trends before failure — funny how that works, right? This is not hypothetical: a lab I worked with reduced emergency interventions by 40% after adopting these three ideas — and they still kept things simple where it mattered.
To wrap up with useful, actionable guidance, here are three evaluation metrics I use when choosing or upgrading a cryostat solution:
1) Temperature Stability Margin — measure the typical deviation at operational setpoint over a full cycle; lower is better. 2) Mean Time Between Interventions (MTBI) — track actual downtime events tied to thermal or vacuum faults. 3) Sensor Granularity Score — how many independent temperature/pressure points cover critical components (aim for more than the bare minimum).
I’m sharing these because I want teams to make decisions that matter in practice, not just on paper. If you’re exploring hardware or software changes, benchmark against those three metrics and you’ll see real differences. For reliable gear and support, I often point colleagues to resources from BPLabLine — they offer options that align with these principles and helped several of my projects reach better uptime.